
Tiled GEMM: Matrix Multiplication in CUDA
Matrix multiplication (C = A × B) is the foundational computational workhorse of modern deep learning, powering everything from Multi-Head Attention projections and Feed-Forward Networks to Mixture-of-Experts routing. Yet, if you implement matrix multiplication on a GPU using a naive one-thread-per-element algorithm, you will typically achieve less than 5% of the device's theoretical peak performance.
The reason is not a lack of arithmetic units; it is the memory wall. In modern GPU architectures, arithmetic throughput vastly outpaces global memory (DRAM) bandwidth. To reach high performance, an algorithm must maximize data reuse by leveraging high-speed, on-chip Shared Memory.
This blog post provides a comprehensive, ground-up guide to Tiled Matrix Multiplication in CUDA, based on the implementation in cuda/tiled_matmuls.cu from the DARK-art108/cuda-experiments repository. We break down the underlying hardware mechanics, walk through every line of the kernel and host code, trace the numerical computations step by step, and examine the path to production-grade GEMM.
1. The Core Bottleneck: Why Naive Matmul Fails
Consider multiplying two N × N square matrices:
C[i, j] = Σ (A[i, k] × B[k, j]) for k = 0 to N - 1
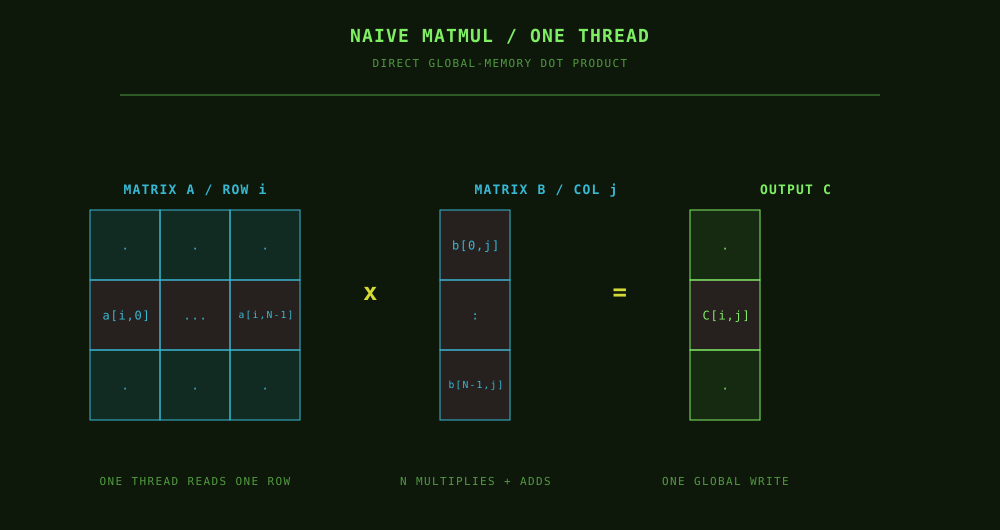
To compute a single element C[i, j], we take the dot product of row i of matrix A and column j of matrix B:
The Arithmetic Intensity Deficit
In a naive CUDA kernel where each thread computes one output C[i, j]:
- Computing
C[i, j]requiresNmultiply-add operations (2NFLOPs). - To perform these operations, the thread fetches
Nfloats from rowiofAandNfloats from columnjofBthrough Global Memory (VRAM / DRAM). - Ignoring the one 4-byte output store, that amounts to
2N × 4 bytes = 8N bytesof input traffic.
The Arithmetic Intensity (I) of this naive approach is:
Arithmetic Intensity (I_naive) = (2N FLOPs) / (8N Bytes) = 0.25 FLOPs / Byte
Now examine the compute-to-bandwidth balance on modern GPUs:
- NVIDIA H100 SXM5: provides ~67 TFLOPs of FP32 vector compute and ~3,350 GB/s of HBM3 bandwidth. Its balance ratio is
67,000 / 3,350 ≈ 20 FLOPs / Byte. - NVIDIA RTX 4090: provides ~82.6 TFLOPs of FP32 compute and ~1,008 GB/s of GDDR6X bandwidth, requiring
82,600 / 1,008 ≈ 82 FLOPs / Byteto keep the math units busy.
With an arithmetic intensity of only 0.25 FLOPs/Byte, the kernel is far below the compute-to-bandwidth balance points above. Under a simple roofline model, memory bandwidth would cap it at roughly 1.25% of the H100's FP32 peak and 0.3% of the RTX 4090's peak, before cache effects and other overheads. This is the memory-bandwidth-bound plateau described by the Roofline Model, not a literal measurement of stalled clock cycles.
Furthermore, adjacent threads computing C[i, j] and C[i, j+1] read the exact same row i of A, yet each issues its own global-memory load for those values. Across the entire grid of N² threads, every element of A and B is requested by N threads; caches may serve some requests without going all the way to DRAM, but the redundant global-memory traffic remains.
2. The Solution: On-Chip Tiling with Shared Memory
To break through the memory wall, we must exploit the GPU's memory hierarchy:
The Tiling Principle
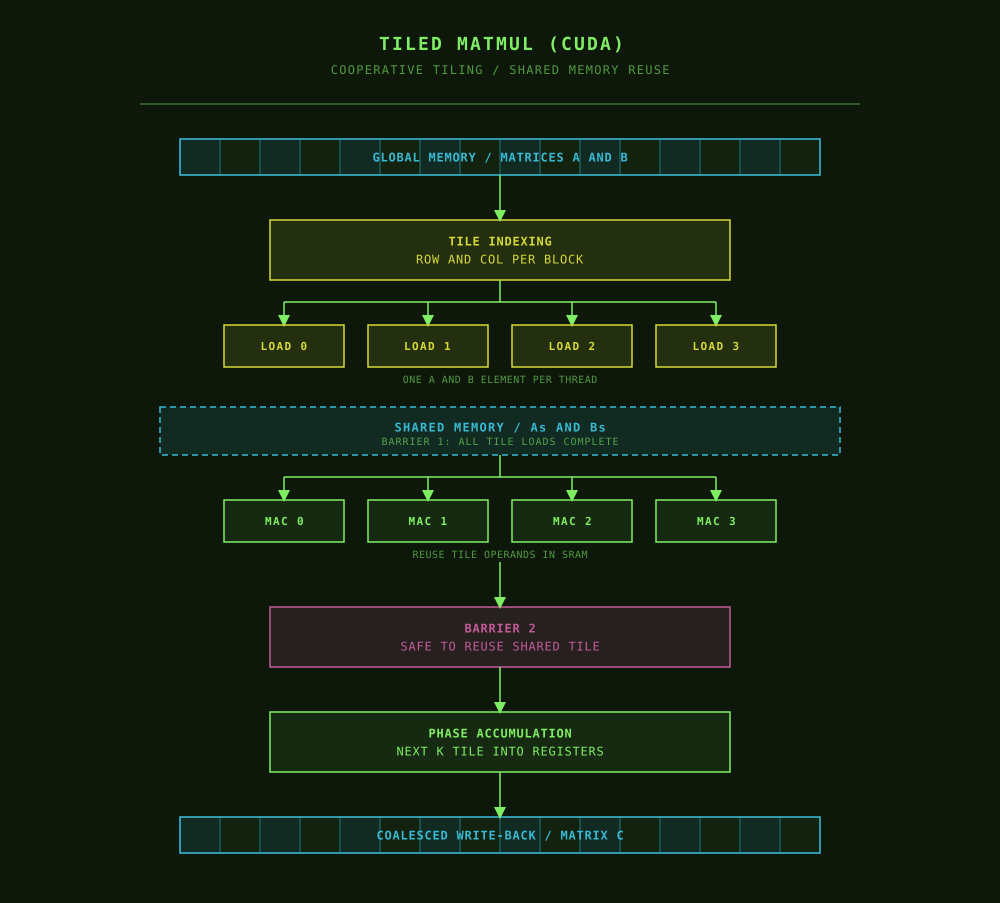
Instead of having each thread load entire rows and columns from global memory across the full matrix dimension K, threads inside a Thread Block collaborate:
- Matrices
AandBare partitioned into 2D sub-matrices called tiles of shapeTILE × TILE. - A thread block of shape
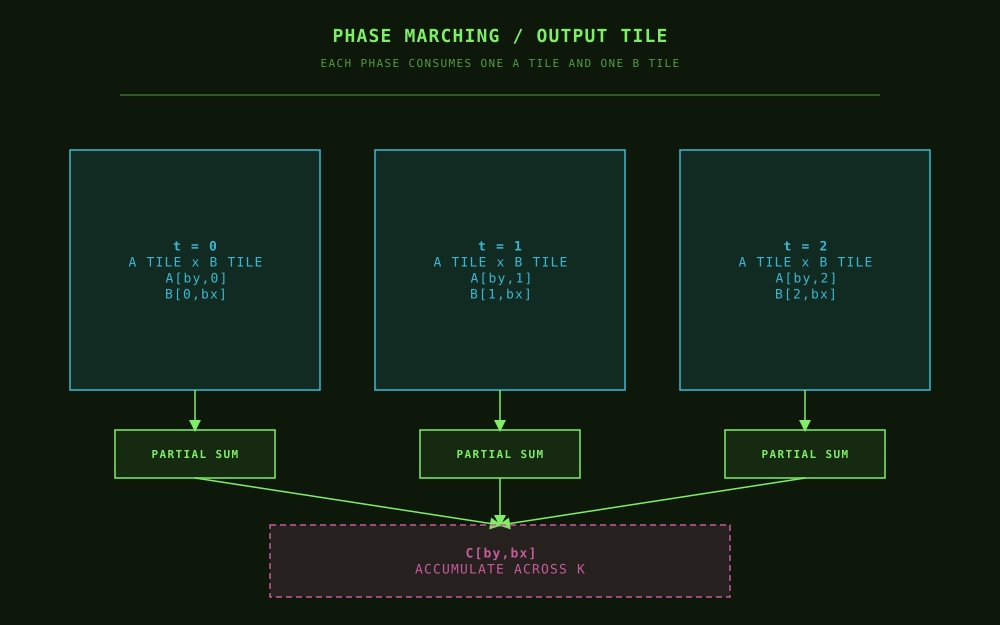
TILE × TILEis assigned to calculate a correspondingTILE × TILEpatch of matrixC. - The calculation proceeds in discrete phases
t = 0, 1, ..., (N / TILE - 1):- Step 1 (Cooperative Load): Each thread in the block loads exactly one element of
A's current tile and one element ofB's current tile from slow global memory into fast, on-chip Shared Memory (AsandBs). - Step 2 (Barrier Synchronization): All threads synchronize (
__syncthreads()) so that the shared memory tile is fully populated before any thread reads from it. - Step 3 (Local Accumulation): Every thread computes a local dot-product of length
TILEentirely out of on-chip shared memory, accumulating the partial result into a private register. - Step 4 (Barrier Synchronization): All threads synchronize again (
__syncthreads()) to guarantee that all threads finish computing before the next iteration overwrites the shared memory tiles.
- Step 1 (Cooperative Load): Each thread in the block loads exactly one element of
- After completing all phases, each thread writes its accumulated scalar back to matrix
Cin global memory.
Why Tiling Multiplies Arithmetic Intensity by TILE
Within a block of size TILE × TILE:
- During one phase, the block loads
TILE²floats fromAandTILE²floats fromBfrom global memory. - Total input bytes loaded from global memory per phase:
2 × TILE² × 4 bytes = 8 · TILE² bytes. - Each of the
TILE²threads performsTILEmultiply-adds (TILEMACs =2 · TILEFLOPs). - Total FLOPs performed by the block per phase:
TILE² × (2 · TILE) = 2 · TILE³ FLOPs.
Ignoring the one output store per result, the arithmetic intensity of the tiled kernel becomes:
Arithmetic Intensity (I_tiled) = (2 · TILE³ FLOPs) / (8 · TILE² Bytes) = (TILE / 4) FLOPs / Byte
Every element loaded from global memory into shared memory is reused TILE times by different threads in the block:
Tile Size (TILE) | Global Memory Traffic Reduction | Arithmetic Intensity (I) |
|---|---|---|
Naive (1) | 1× (None) | 0.25 FLOPs / Byte |
| 2 (Pedagogical) | 2× | 0.50 FLOPs / Byte |
| 16 | 16× | 4.00 FLOPs / Byte |
| 32 | 32× | 8.00 FLOPs / Byte |
By setting TILE = 32, we reduce the A and B input-load traffic by about 96.9% compared with the naive per-output loads. The output stores still occur once per element.
3. Complete Source Code: tiled_matmuls.cu
Below is the complete implementation from DARK-art108/cuda-experiments/cuda/tiled_matmuls.cu:
#include <cuda_runtime.h>
#include <stdio.h>

#define TILE 2

__global__
void matmul_tiled(float *A, float *B, float *C, int N)
{
    __shared__ float As[TILE][TILE];
    __shared__ float Bs[TILE][TILE];

    int row = blockIdx.y * TILE + threadIdx.y;
    int col = blockIdx.x * TILE + threadIdx.x;
    float sum = 0.0f;

    for (int t = 0; t < N / TILE; t++)
    {
        As[threadIdx.y][threadIdx.x] = A[row * N + t * TILE + threadIdx.x];
        Bs[threadIdx.y][threadIdx.x] = B[(t * TILE + threadIdx.y) * N + col];

        __syncthreads();

        for (int k = 0; k < TILE; k++)
        {
            sum += As[threadIdx.y][k] * Bs[k][threadIdx.x];
        }

        __syncthreads();
    }

    if (row < N && col < N)
        C[row * N + col] = sum;
}

int main()
{
    const int N = 4;
    const int matsize = 16;

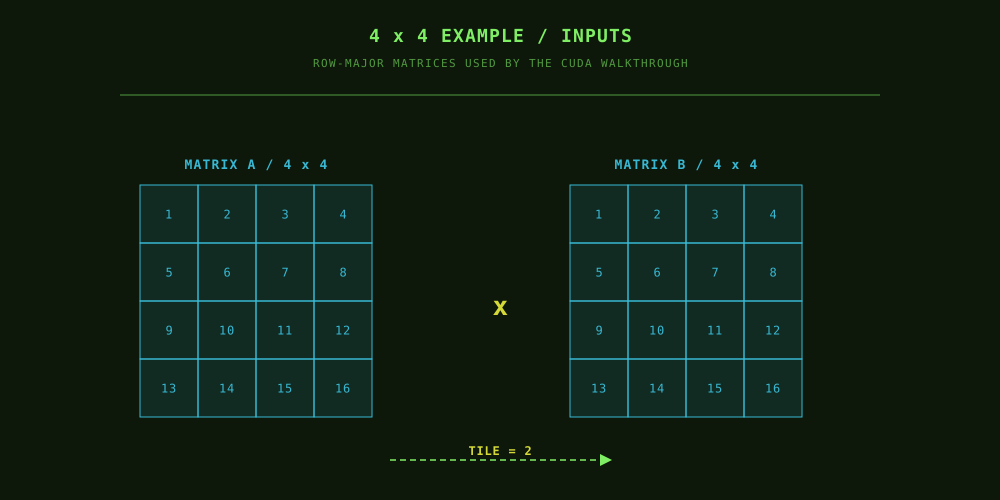
    float A[matsize] = {
         1,  2,  3,  4,
         5,  6,  7,  8,
         9, 10, 11, 12,
        13, 14, 15, 16
    };

    float B[matsize] = {
         1,  2,  3,  4,
         5,  6,  7,  8,
         9, 10, 11, 12,
        13, 14, 15, 16
    };

    float C[matsize] = {0};

    float *d_A, *d_B, *d_C;
    cudaMalloc(&d_A, matsize * sizeof(float));
    cudaMalloc(&d_B, matsize * sizeof(float));
    cudaMalloc(&d_C, matsize * sizeof(float));

    cudaMemcpy(d_A, A, matsize * sizeof(float), cudaMemcpyHostToDevice);
    cudaMemcpy(d_B, B, matsize * sizeof(float), cudaMemcpyHostToDevice);

    // grid  = (2,2) -> 4 blocks
    // block = (2,2) -> 4 threads/block
    // total = 4 x 4 = 16 threads

    dim3 block(TILE, TILE);
    dim3 grid(N / TILE, N / TILE);

    matmul_tiled<<<grid, block>>>(d_A, d_B, d_C, N);

    cudaMemcpy(C, d_C, matsize * sizeof(float), cudaMemcpyDeviceToHost);

    for (int i = 0; i < N; i++)
    {
        for (int j = 0; j < N; j++)
            printf("%6.0f", C[i * N + j]);
        printf("\n");
    }

    cudaFree(d_A);
    cudaFree(d_B);
    cudaFree(d_C);

    return 0;
}
The choice of N = 4 and TILE = 2 in this experiment is intentionally minimal and pedagogical: it allows us to track every register, shared memory cell, and DRAM address by hand without getting lost in thousands of indices.
This educational version assumes N is divisible by TILE, which is true for the example. The boundary-guarded version in the production-hardening section is required for arbitrary dimensions.
4. Deep-Dive Kernel Anatomy
Let us dissect the matmul_tiled kernel line by line to understand the hardware-software interaction.
4.1 Shared Memory Declaration
__shared__ float As[TILE][TILE];
__shared__ float Bs[TILE][TILE];
- The
__shared__qualifier instructsnvccto allocate these 2D arrays in the SM's on-chip SRAM (the L1/Shared Memory pool). - Scope & Lifetime: Shared memory is allocated per thread block. All threads within the same thread block share access to
AsandBs. Different thread blocks have completely separate, isolated shared memory allocations. - Footprint: For
TILE = 2, each array consumes2 × 2 × 4 bytes = 16 bytes, totaling32 bytesof shared memory per block. For a standard block size ofTILE = 32, each array consumes32 × 32 × 4 = 4 KB, totaling8 KBper block, well within typical SM capacity limits (48 KB to 228 KB).
4.2 Thread Coordinate Calculation
int row = blockIdx.y * TILE + threadIdx.y;
int col = blockIdx.x * TILE + threadIdx.x;
float sum = 0.0f;
CUDA grids and thread blocks can be multi-dimensional (using dim3). Here:
threadIdx.xandthreadIdx.yidentify the thread's local position inside its tile:threadIdx.x ∈ [0, TILE - 1],threadIdx.y ∈ [0, TILE - 1].blockIdx.xandblockIdx.yidentify which spatial tile of matrixCthis block computes.rowandcolmap directly to row and column coordinates in global matrixC:row = blockIdx.y * TILE + threadIdx.ycol = blockIdx.x * TILE + threadIdx.x
sumis a private, per-thread scalar that the compiler can keep in the thread's register file. In this small kernel it should remain register-resident, but production kernels must account for possible register pressure and spills.
4.3 The Outer Phase Loop
for (int t = 0; t < N / TILE; t++)
Matrix multiplication requires computing a dot-product along dimension K of length N. Since our tile has width TILE, we divide the dimension into discrete phases:
num_phases = N / TILE
For N = 4 and TILE = 2, this loop executes exactly 4 / 2 = 2 iterations (t = 0 and t = 1).
4.4 Cooperative Shared Memory Loading & Coalescing
Inside the loop, the block collaborates to populate As and Bs:
As[threadIdx.y][threadIdx.x] = A[row * N + t * TILE + threadIdx.x];
Bs[threadIdx.y][threadIdx.x] = B[(t * TILE + threadIdx.y) * N + col];
Each thread loads exactly one float into As and one float into Bs. Let us analyze the global memory addressing:
Addressing for Matrix A:
Index_A = row * N + (t * TILE + threadIdx.x)
rowdepends only onblockIdx.yandthreadIdx.y. For all threads with the samethreadIdx.y(threads in the same horizontal row of the block),rowis identical.- As
threadIdx.xincrements by 1 (0 -> 1), the memory offset increments by 1 float (4 bytes). - Result: Consecutive participating threads access consecutive 4-byte words. When a full warp covers a row, as it does for a
TILE = 32production tile, this becomes a fully coalesced warp access; the pedagogicalTILE = 2block only has four participating threads (see Memory Coalescing).
Addressing for Matrix B:
Index_B = (t * TILE + threadIdx.y) * N + col
        = (t * TILE + threadIdx.y) * N + blockIdx.x * TILE + threadIdx.x
- As
threadIdx.xincrements by 1, the column index increments by 1, so the accessed memory address also increments by 4 bytes. - Result: The participating threads access consecutive locations; a full warp-sized tile produces the expected coalesced access pattern.
4.5 The First Barrier: Preventing RAW Hazards
__syncthreads();
Why is __syncthreads() mandatory here?
- In CUDA, threads within a block execute asynchronously across warps. There is no guarantee that Thread 0 and Thread 3 execute instructions at the same speed.
- If Thread 0 finishes loading
As[0][0]and immediately proceeds to the math loop, it might readBs[1][0], which is supposed to be loaded by Thread 2. If Thread 2 has not finished its global load yet, Thread 0 will read uninitialized shared memory or stale data. - This is a Read-After-Write (RAW) hazard.
__syncthreads()creates a hardware barrier: every thread in the block must reach this line before any thread is allowed to proceed. When the barrier clears,AsandBsare guaranteed to contain valid, fresh data for phaset.
4.6 On-Chip Tile Matrix Multiplication
for (int k = 0; k < TILE; k++)
{
    sum += As[threadIdx.y][k] * Bs[k][threadIdx.x];
}
Now, every thread calculates its partial dot product:
- Thread
(threadIdx.y, threadIdx.x)reads rowthreadIdx.yofAsand columnthreadIdx.xofBs. - Both operands reside in shared memory SRAM, which provides much lower latency and much higher effective bandwidth than repeated global-memory loads.
- No global memory buses are touched. The Multiply-Accumulate (MAC) pipeline runs at peak efficiency.
4.7 The Second Barrier: Preventing WAR Hazards
__syncthreads();
Why is this second barrier equally critical?
- Consider what happens at the end of phase
t: Thread 0 might compute its inner loop very fast and immediately loop around to phaset + 1, where it executes:As[0][0] = A[...] - Meanwhile, Thread 3 might still be finishing the inner loop of phase
t, needing the old value ofAs[0][0]. - If Thread 0 overwrites
As[0][0]before Thread 3 finishes reading it, Thread 3's calculation is corrupted. - This is a Write-After-Read (WAR) hazard.
- The second
__syncthreads()guarantees that all threads have completely finished consuming the tiles of phasetbefore any thread starts overwriting shared memory with the tiles of phaset + 1.
4.8 Write-Back to Global Memory
if (row < N && col < N)
    C[row * N + col] = sum;
Once all phases are complete, sum holds the final dot product for output element C[row, col]:
- Each thread performs a single global memory write to store its result.
- Because
col = blockIdx.x * TILE + threadIdx.x, consecutive participating threads write to consecutive global memory addresses. With a warp-sized row this is a coalesced write; the smallTILE = 2example only demonstrates the contiguous addressing pattern.
5. End-to-End Walkthrough of the 4 × 4 Example
Let us trace the exact numbers from the host code in tiled_matmuls.cu:
Input Matrices
Grid and Block Layout
dim3 block(TILE, TILE);        // (2, 2) -> 4 threads per block
dim3 grid(N / TILE, N / TILE); // (2, 2) -> 4 blocks in grid
The execution grid consists of 4 blocks, arranged as a 2 × 2 grid:
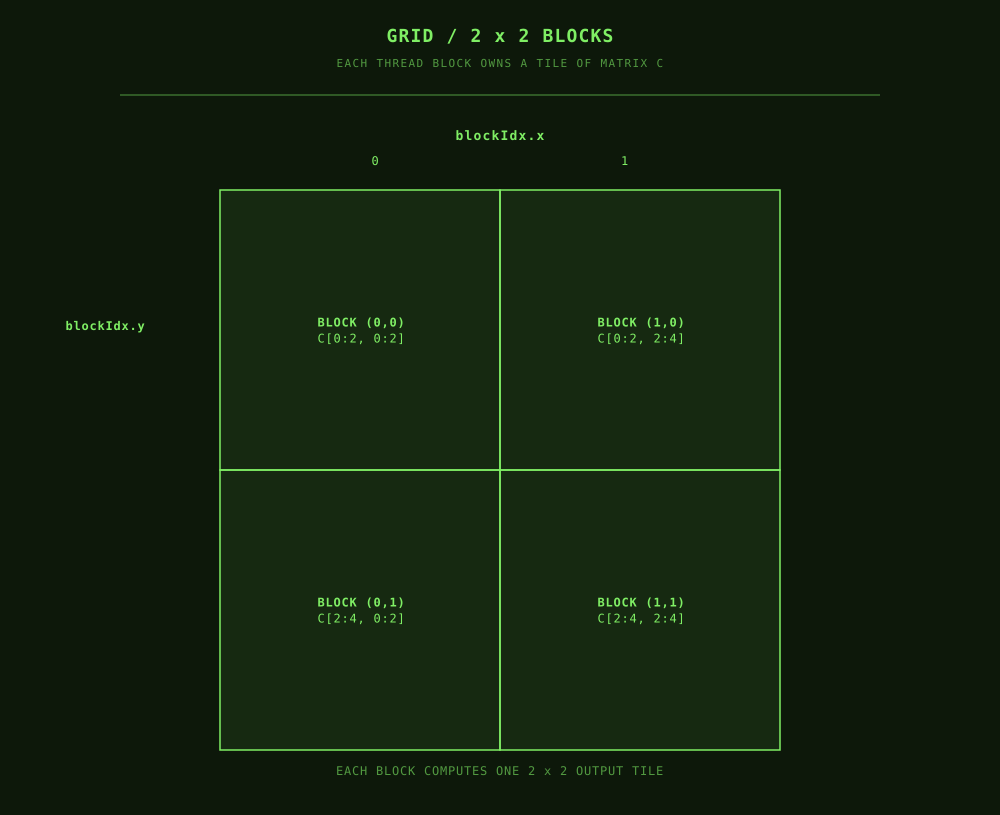
Each block has 4 threads:
- Thread
(0, 0): computes top-left element of block - Thread
(1, 0): computes top-right element of block - Thread
(0, 1): computes bottom-left element of block - Thread
(1, 1): computes bottom-right element of block
(Note: In CUDA coordinates, threadIdx.x is column index, threadIdx.y is row index).
Step-by-Step Numerical Trace for Block (0, 0)
Block (0, 0) has blockIdx.x = 0 and blockIdx.y = 0. It computes C[0..1, 0..1].
Phase t = 0:
1. Cooperative Shared Memory Load:
- Thread
(0, 0)(row=0, col=0):As[0][0] = A[0*4 + 0*2 + 0] = A[0] = 1Bs[0][0] = B[(0*2 + 0)*4 + 0] = B[0] = 1
- Thread
(1, 0)(row=0, col=1):As[0][1] = A[0*4 + 0*2 + 1] = A[1] = 2Bs[0][1] = B[(0*2 + 0)*4 + 1] = B[1] = 2
- Thread
(0, 1)(row=1, col=0):As[1][0] = A[1*4 + 0*2 + 0] = A[4] = 5Bs[1][0] = B[(0*2 + 1)*4 + 0] = B[4] = 5
- Thread
(1, 1)(row=1, col=1):As[1][1] = A[1*4 + 0*2 + 1] = A[5] = 6Bs[1][1] = B[(0*2 + 1)*4 + 1] = B[5] = 6
Shared memory contents after __syncthreads():
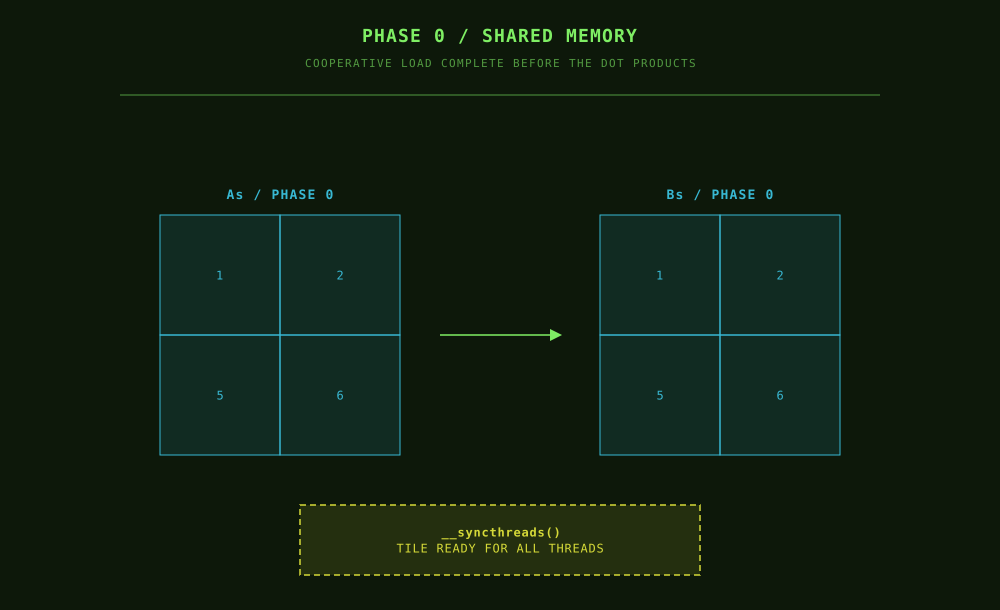
2. Compute Partial Dot-Products:
- Thread
(0, 0):sum += As[0][0]·Bs[0][0] + As[0][1]·Bs[1][0] = 1·1 + 2·5 = 1 + 10 = 11 - Thread
(1, 0):sum += As[0][0]·Bs[0][1] + As[0][1]·Bs[1][1] = 1·2 + 2·6 = 2 + 12 = 14 - Thread
(0, 1):sum += As[1][0]·Bs[0][0] + As[1][1]·Bs[1][0] = 5·1 + 6·5 = 5 + 30 = 35 - Thread
(1, 1):sum += As[1][0]·Bs[0][1] + As[1][1]·Bs[1][1] = 5·2 + 6·6 = 10 + 36 = 46
Phase t = 1:
1. Cooperative Shared Memory Load (t · TILE = 2):
- Thread
(0, 0):As[0][0] = A[0*4 + 2 + 0] = A[2] = 3Bs[0][0] = B[(2 + 0)*4 + 0] = B[8] = 9
- Thread
(1, 0):As[0][1] = A[0*4 + 2 + 1] = A[3] = 4Bs[0][1] = B[(2 + 0)*4 + 1] = B[9] = 10
- Thread
(0, 1):As[1][0] = A[1*4 + 2 + 0] = A[6] = 7Bs[1][0] = B[(2 + 1)*4 + 0] = B[12] = 13
- Thread
(1, 1):As[1][1] = A[1*4 + 2 + 1] = A[7] = 8Bs[1][1] = B[(2 + 1)*4 + 1] = B[13] = 14
Shared memory contents after __syncthreads():
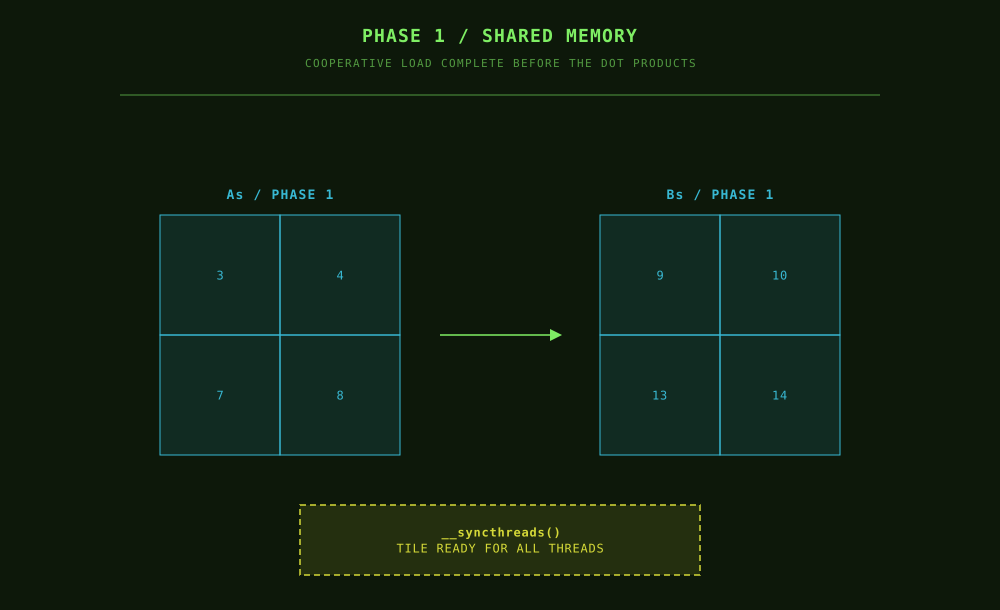
2. Accumulate Partial Dot-Products:
- Thread
(0, 0):sum = 11 + (As[0][0]·Bs[0][0] + As[0][1]·Bs[1][0]) = 11 + (3·9 + 4·13) = 11 + 27 + 52 = 90 - Thread
(1, 0):sum = 14 + (As[0][0]·Bs[0][1] + As[0][1]·Bs[1][1]) = 14 + (3·10 + 4·14) = 14 + 30 + 56 = 100 - Thread
(0, 1):sum = 35 + (As[1][0]·Bs[0][0] + As[1][1]·Bs[1][0]) = 35 + (7·9 + 8·13) = 35 + 63 + 104 = 202 - Thread
(1, 1):sum = 46 + (As[1][0]·Bs[0][1] + As[1][1]·Bs[1][1]) = 46 + (7·10 + 8·14) = 46 + 70 + 112 = 228
Final Matrix Verification
Applying the same process across all 4 blocks yields the exact matrix C:
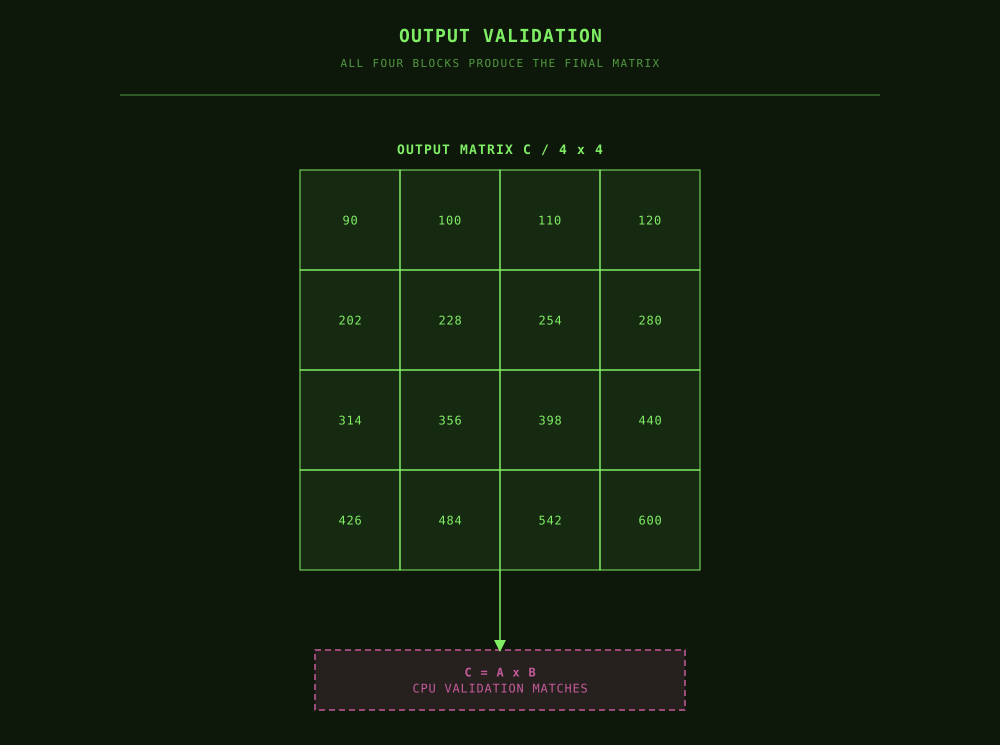
This matches the CPU validation and mathematical matrix product A × B with bit-level precision.
6. Host-Side Workflow: Allocations and Transfers
The host main() function illustrates standard CUDA memory management:
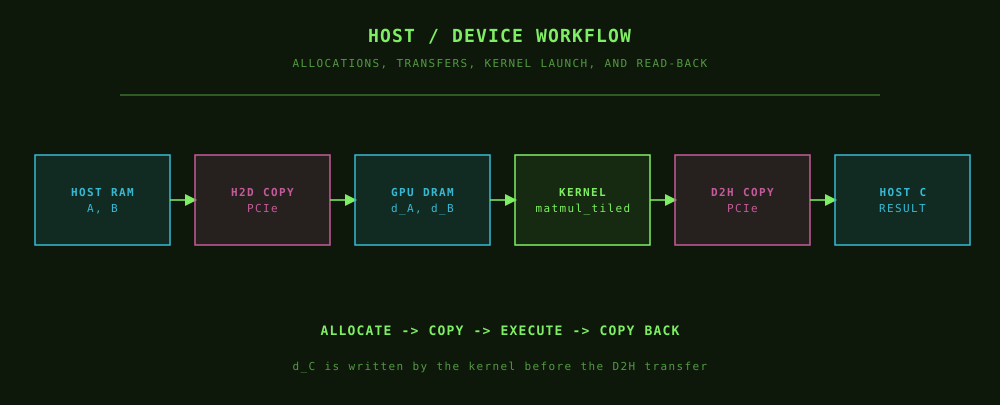
Steps Explained:
- Host Allocation & Data Initialization:
Matrices
AandBare allocated as contiguous row-major arrays of 16 floats. - Device Memory Allocation (
cudaMalloc):
Allocates contiguous physical memory buffers in the GPU's high-bandwidth device memory.cudaMalloc(&d_A, matsize * sizeof(float)); cudaMalloc(&d_B, matsize * sizeof(float)); cudaMalloc(&d_C, matsize * sizeof(float)); - Data Transfer (
cudaMemcpyHostToDevice): Transfers matricesAandBfrom system RAM over the PCIe bus into GPU global memory. - Kernel Launch (
<<<grid, block>>>): Enqueues the kernel for asynchronous execution on the GPU's default stream. - Result Read-Back (
cudaMemcpyDeviceToHost): Blocks host execution until the kernel finishes, then transfers matrixd_Cback to CPU memory. - Resource Cleanup (
cudaFree): Frees device memory to avoid memory leaks.
7. Production Hardening: Beyond the 2 × 2 Example
While the educational kernel in tiled_matmuls.cu illustrates the core algorithm, production-grade matrix multiplication introduces several real-world engineering constraints:
7.1 Handling Arbitrary Matrix Dimensions (Ragged Edges)
The basic code assumes N is an exact multiple of TILE. When N is not divisible by TILE (e.g., N = 1000 with TILE = 32), the grid must round up using ceiling division:
dim3 grid((N + TILE - 1) / TILE, (M + TILE - 1) / TILE);
When threads near the matrix boundary execute, their global load indices may exceed matrix dimensions. In that case, loads must be boundary-guarded with zeros to avoid illegal memory accesses while keeping the inner dot-product mathematically valid:
int aCol = t * TILE + threadIdx.x;
int bRow = t * TILE + threadIdx.y;

As[threadIdx.y][threadIdx.x] = (row < M && aCol < K) ? A[row * K + aCol] : 0.0f;
Bs[threadIdx.y][threadIdx.x] = (bRow < K && col < N) ? B[bRow * N + col] : 0.0f;
Zero-padding ensures that out-of-bound elements contribute 0.0 × ... = 0 to the accumulator without corrupting the sum.
7.2 Shared Memory Bank Conflicts
On modern NVIDIA architectures, shared memory is divided into 32 independent memory banks (each 4 bytes / 32 bits wide).
- If multiple threads in a warp access different addresses within the same memory bank simultaneously, the hardware must serialize the accesses, causing a bank conflict (see Bank Conflicts).
- If all threads access the exact same address, the hardware performs a zero-penalty broadcast.
In the inner loop:
sum += As[threadIdx.y][k] * Bs[k][threadIdx.x];
- For
As[threadIdx.y][k]: all threads in a warp with the samethreadIdx.yaccess the same elementAs[threadIdx.y][k]. This is a hardware broadcast (conflict-free). - For
Bs[k][threadIdx.x]: threadiin a 1D warp accessesBs[k][i]. Since columnimaps to memory banki mod 32, threads0..31access 32 distinct banks simultaneously. This is also completely conflict-free.
However, when transposing matrices or loading larger tiles, developers frequently add a 1-element pad to the leading dimension of shared memory arrays to avoid bank alignment issues:
__shared__ float As[TILE][TILE + 1]; // Eliminates bank conflicts in transposed loads
8. The Modern GEMM Hierarchy: From Tiling to CUTLASS
Tiled matrix multiplication using shared memory is the foundational building block of all modern high-performance linear algebra libraries (such as cuBLAS, CUTLASS, and CuTe). Production kernels take this concept through a multi-level hierarchy:
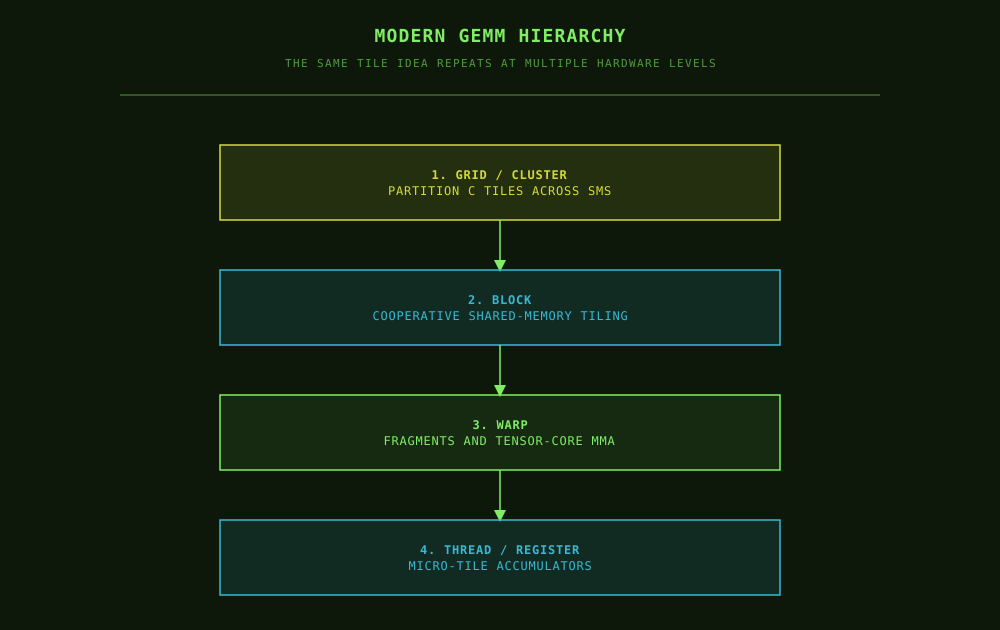
Modern Acceleration Techniques:
- Async Copy (
cp.async): Introduced in the Ampere architecture (Compute Capability 8.0+), allows the GPU to copy data directly from Global Memory into Shared Memory without staging it through thread registers. - Double Buffering / Software Pipelining: Overlaps the global memory transfer for phase
t + 1with the math computation of phaset, hiding memory latency almost entirely. - TMA (Tensor Memory Accelerator): Introduced in Hopper (H100) and Blackwell, dedicated hardware units handle multi-dimensional tensor copies asynchronously between global and shared memory without using SM ALU instructions.
9. Summary & Key Takeaways
- Naive Matmul is Bandwidth-Starved: Computing matrix multiplication with direct global memory fetches wastes >95% of compute capacity due to low arithmetic intensity (
0.25 FLOPs/Byte). - Tiling Multiplies Reuse: Loading
TILE × TILEchunks into on-chip shared memory reduces global DRAM access by a factor ofTILE, increasing arithmetic intensity to(TILE / 4) FLOPs/Byte. - Coalesced Memory Access: Ensuring consecutive threads in a warp load consecutive memory addresses eliminates bus transaction waste.
- Dual Synchronization Barriers:
- The first
__syncthreads()prevents Read-After-Write (RAW) data races before computation begins. - The second
__syncthreads()prevents Write-After-Read (WAR) data races before the next tile overwrites shared memory.
- The first
References & Further Reading
- Code Source:
cuda/tiled_matmuls.cuin DARK-art108/cuda-experiments. - NVIDIA Documentation: CUDA C++ Programming Guide, Shared Memory.
- Textbook Reference: David B. Kirk and Wen-mei W. Hwu, Programming Massively Parallel Processors: A Hands-on Approach (PMPP), Chapter 4: "Memory Architecture and Data Locality".
- Related Glossary Notes:
- CUDA Kernel, kernel launch fundamentals, grid geometry, and indexing.
- Shared Memory, hardware layout and usage patterns.
- Arithmetic Intensity, quantifying compute vs memory bounds.
- Roofline Model, visual performance modeling for GPU kernels.
- Memory Coalescing, coalescing rules and transaction metrics.
- Bank Conflict, shared memory bank architecture and resolution.
About the author
Ritesh Yadav works as an AI/ML Engineer. He writes independent research notes on ML performance, infrastructure, and systems, covering CUDA, low-latency inference, generative AI, distributed training, Kubernetes, and LLMOps.